Tokens Are the New Lines of Code
Tokenmaxxing might be the ugliest new word of 2026. A New York Times column by Kevin Roose in March 2026 used it to describe internal leaderboards that ranked employees by how many AI tokens they consumed. One engineer reportedly ran through 210 billion tokens. In May 2026, Forbes reported that Uber had run leaderboards ranking engineers by AI coding activity. Then in September 2026, The Decoder, citing The Information, reported that Meta had told its engineers that AI dashboards and token counts would no longer factor into performance reviews. Reviews would focus on the quality, speed, and complexity of the work instead.
I’m glad at least one big company walked it back. However, I suspect plenty of review templates still include some version of “uses AI tools effectively,” quietly measured by a usage number.
Our industry has been here before. For years, people tried to measure programmer productivity by lines of code. It took a long time for everyone to admit the obvious: the engineer who deletes a pile of code and fixes the bug is often worth more than the one who adds a pile and creates new bugs. When you reward volume, you get volume.
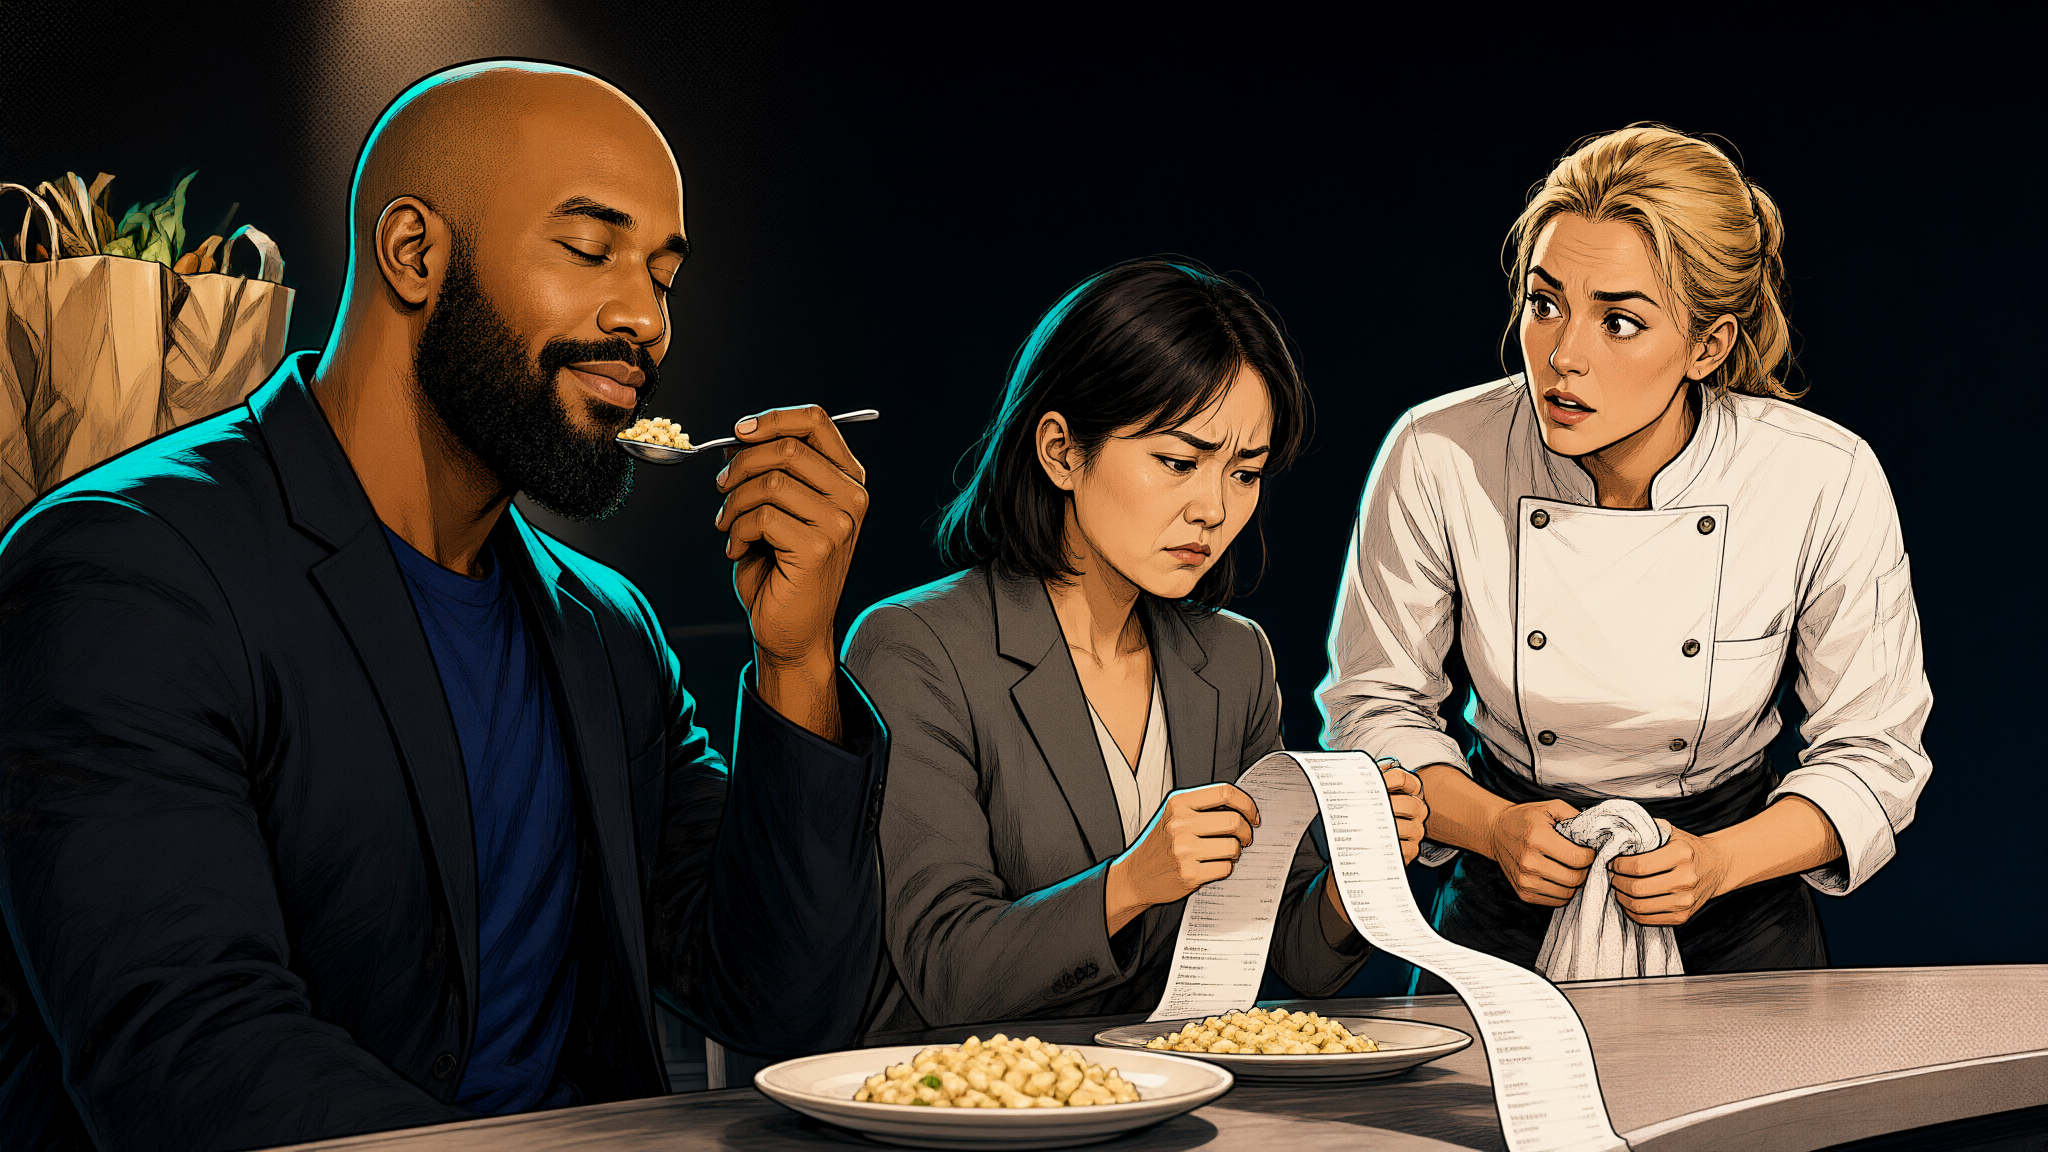
Here’s how I’d put it. Judging an engineer by token use is like judging a chef by the grocery bill. A big grocery bill could mean the chef is feeding a lot of people. It could also mean they burned three pots of risotto and started over each time. The bill tells you about inputs. You still have to taste the food.
I want to be fair here, because I’m not against counting usage. If you can’t count usage, you can’t defend a tool when someone asks what it’s for, and AI tools are expensive enough that someone will ask. So, companies should absolutely know how much they spend on AI tools and which teams use them. That tells you whether the tool is serving the team or the other way around.
What usage can’t tell you is whether a person is good at their job.
The best evidence about my own work has never been a count. Not long after becoming a software engineering manager, a company-wide employee survey recognized me as a people developer, and the comment with it said I was “a great mentor and leader that is always available to help me tackle project related issues.” Nobody counted my emails that year or how many documents I opened. Someone described what changed for them because I was around. That’s the kind of evidence a review should rest on.
So, if AI shows up in your reviews, here’s what I’d suggest.
Review the decision, and leave the consumption out of it. Ask people to describe a problem where AI helped and one where they chose not to use it. Judgment includes knowing when a tool is wrong for the job, and the second story usually tells you more than the first.
Look at outcomes, including who cleaned up after them. In LeadDev’s annual survey of engineering leaders, published in June 2026, the top AI worries were code maintainability (73%) and output quality (71%). If someone ships fast and their teammates spend the next sprint fixing it, that should show up somewhere in the review.
Keep the leaderboard away from the review. If you want to know who’s experimenting, ask in a one-on-one, and ask with curiosity. Leaderboards produce fear-driven adoption. Good one-on-ones and career conversations produce the kind that lasts.
People will optimize for whatever you measure and game those measures into irrevalency. So, before review season gets busy, look at your template and verify that the thing you’re measuring is the thing we actually want?